- BuildPadAI rapid application development for secure, tailored internal tools.
- Chocolate FactoryAgentic AI platform to observe, teach and configure your agents.
- Cloud PrimusOne control plane for AI and cloud, with cost control built in.
- SentryPageIntelligent website defacement monitoring that catches changes fast.
- VisorOne AI-powered CMS for every enterprise website you run.
Financial crime alert review
The problem
A transaction monitoring system generates thousands of alerts a month and the large majority are false positives. Analysts spend most of their time assembling the same evidence pack for each one: customer profile, account history, counterparty details, prior alerts, adverse media. Level 1 review is largely clerical work, yet it sets the queue that Level 2 and the MLRO depend on, so a backlog pushes real cases later. Every disposition has to be explainable years after the fact, which rules out any tool that returns a recommendation without showing the evidence and the reasoning that produced it. Analyst turnover means review quality varies by who was on shift.
The solution
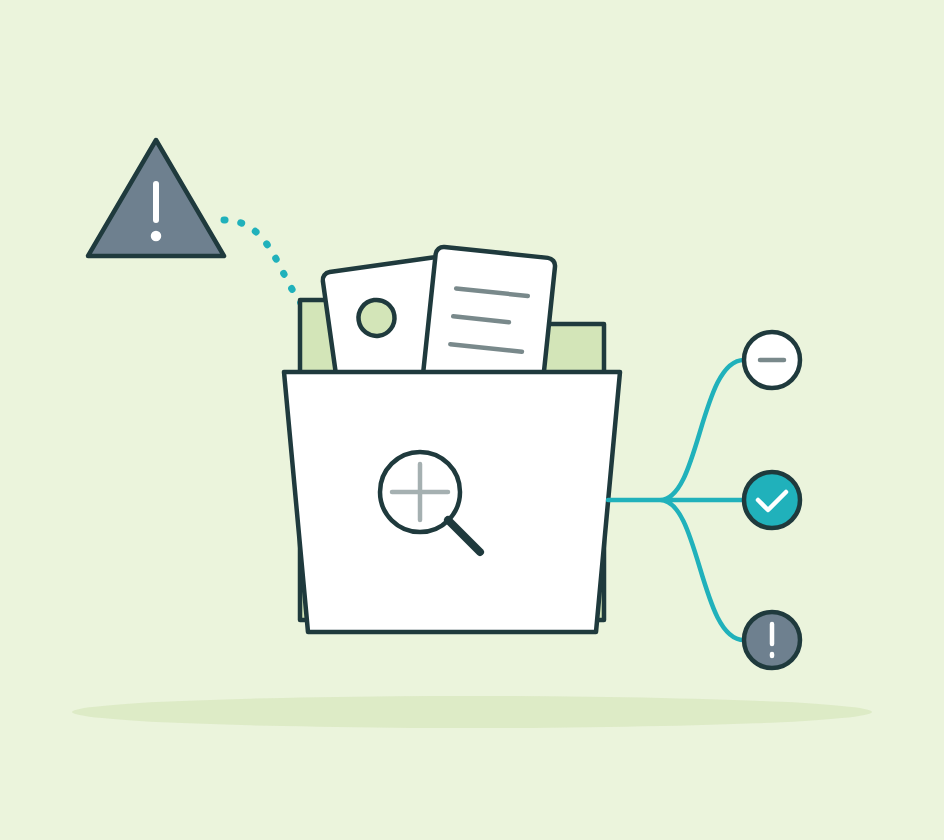
A review agent that takes each alert, assembles the evidence pack from the systems of record, applies the institution's own typology and escalation rules, and returns a recommended disposition with the evidence cited against each point. The analyst decides. The agent never closes an alert.
How Chocolate Factory does it
- Core banking, KYC, and case management connect read-only; sanctions and adverse-media screening connect as MCP servers with health indicators.
- Knowledge bases hold AML policy, the typology library, escalation thresholds, and prior STR narratives, so the thresholds in force are the ones applied.
- Two agents: one assembles the evidence pack, one reasons over it against policy, so the reasoning can be re-run without re-querying source systems.
- The monitoring system posts each alert to /execute; a Branch routes it to false positive, analyst review, or immediate escalation.
- Every run leaves a trace of each retrieval and tool call, which serves as the audit record, and tokens by project give cost per alert.
What changes
The analyst's work starts at judgement, with the evidence pack assembled and the policy already applied. Disposition reasoning becomes consistent across shifts, because the same policy version and typology library produce it every time, and escalations reach Level 2 with the pack attached, so the same evidence is not gathered twice. Explainability stops depending on how well an analyst wrote their notes, since the trace holds the retrieval and the reasoning behind every alert, including the ones closed as false positives. A threshold change takes effect by re-syncing a knowledge base, and the traces either side of it show which version applied to which alert. Queue depth stops setting the review standard, so backlog and review quality stop trading against each other.